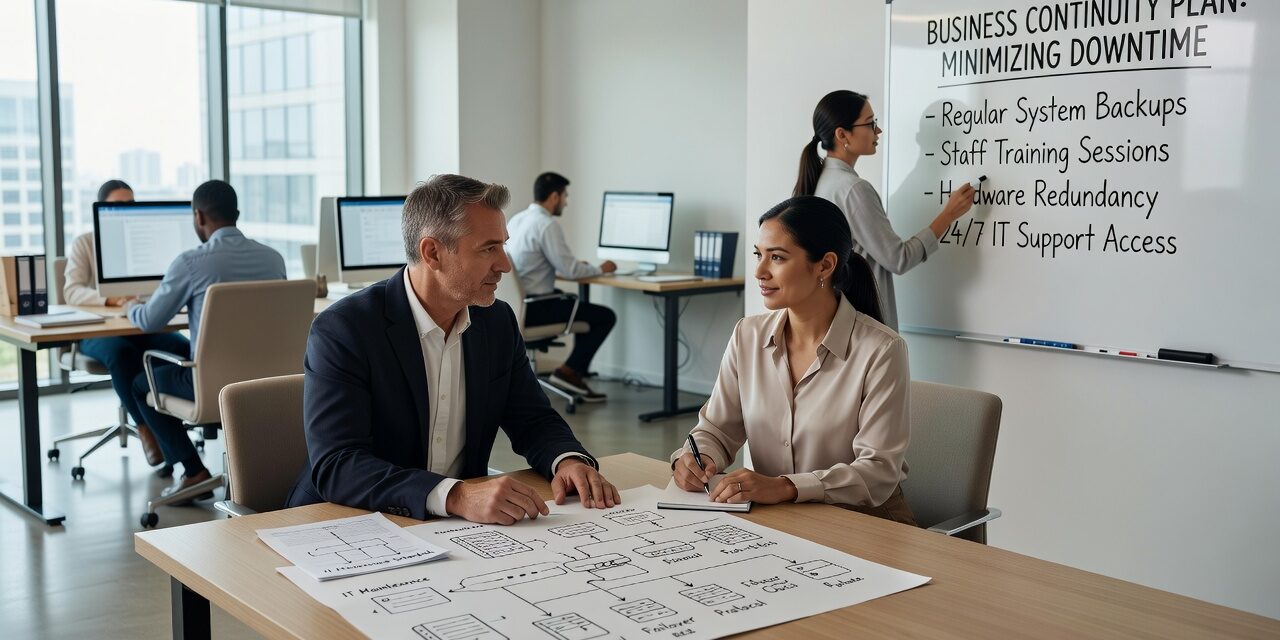
Downtime rarely announces itself in advance. A router fails on a Tuesday morning. A Microsoft 365 outage locks your team out of email for two hours. A backup that ran every night for six months turns out to be corrupt when you actually need it. These are not rare edge cases — they are the kinds of IT problems that quietly drain productivity and create real business costs. If you want to reduce business downtime from IT issues, the fix usually isn’t one big purchase. It’s closing a handful of gaps that most growing organizations overlook.
The Most Common IT Gaps That Lead to Downtime
Most downtime doesn’t come from dramatic failures. It comes from deferred maintenance, unclear ownership, and the assumption that something is working because no one has complained about it yet.
A few patterns that show up repeatedly:
- No one owns the monitoring. If your team only finds out about a network problem after employees start calling in, that’s reactive IT. By the time someone escalates it, the outage is already underway.
- Aging network equipment left in place. Routers, switches, and firewalls that haven’t been patched or replaced on a reasonable schedule are both a reliability risk and a security risk. A router running years-old firmware is not a stable foundation for a business network.
- IT split between too many vendors. When your internet provider, your software vendor, and a break-fix contractor all blame each other during an incident, nothing gets resolved quickly. Unclear vendor ownership extends outages.
- No tested recovery process. Backup jobs completing successfully does not mean your data is recoverable. A backup that has never been tested is a guess, not a plan.
Any one of these gaps can cause an outage. Several of them together make outages nearly unavoidable.
Why Backup and Recovery Deserves More Attention Than It Gets
Most small businesses have *some* form of backup running. Far fewer have confirmed that it actually works.
There’s an important distinction worth understanding: a backup job completing means files were copied somewhere. A successful recovery means those files can be restored to a working system within a timeframe your business can tolerate. Those are two different things.
Two terms that matter here are RTO (Recovery Time Objective) and RPO (Recovery Point Objective). RTO is how long your business can afford to be down before it causes serious harm. RPO is how much data you can afford to lose — measured in hours or days, not just in gigabytes. If your RTO is four hours but your current recovery process takes two days, you have a gap that only becomes visible during an actual incident.
Businesses that don’t test their backups regularly often discover this gap at the worst possible time — after ransomware, after a hardware failure, or after an employee accidentally deletes a shared folder that others depended on.
A practical rule: test your recovery process at least quarterly. If your current IT support can’t show you documentation that a real restoration was performed, that’s a conversation worth having.
Response Time vs. Resolution Time: A Common Blind Spot
Many businesses track whether IT support *responded* to a ticket. Fewer track whether the problem was actually *resolved*, and how long it took.
Response time — how fast someone acknowledges the issue — is easy to measure and easy to look good on. Resolution time — how long until the employee or system is fully functional again — is what actually affects your operations.
A help desk that responds to every ticket in 15 minutes but takes two days to fix recurring issues isn’t performing well. It’s just communicating quickly.
If you manage an IT support agreement, or are evaluating one, ask for resolution time data by issue type. Look for patterns in recurring tickets — the same printer, the same VPN connection, the same Microsoft 365 login problem appearing week after week. Recurring tickets are a signal that something isn’t being resolved at the root cause. They’re also a reliable predictor of future downtime.
Network Reliability: Small Issues That Become Big Outages
Network problems are one of the most common sources of unplanned downtime, and also one of the most preventable.
Consider a scenario that plays out regularly in small office environments: a business has been running on the same firewall for six or seven years. It’s never caused a visible problem, so no one has thought about replacing it. Then one afternoon, VPN connections start dropping for remote employees, Wi-Fi becomes intermittent, and the office internet feels sluggish. The problem gets escalated, and an IT technician discovers the device has been running unsupported firmware for over two years and is now causing intermittent packet loss.
That outage was preventable. Not with expensive hardware, but with a basic equipment review that should have happened before the device became a problem.
Some practical steps that reduce network-related downtime:
- Review firewall and router firmware regularly. If your network equipment hasn’t received a firmware update in more than a year, treat it as an open risk.
- Replace consumer-grade hardware used in a business setting. Consumer routers weren’t designed for the traffic patterns, VPN loads, or uptime requirements of a business network.
- Separate guest Wi-Fi from internal systems. This is both a reliability and security measure.
- Have a documented escalation path for internet outages. Who calls the ISP? What’s the backup connectivity option? If no one knows the answer, the outage will be longer than it needs to be.
Deciding Between Reactive and Proactive IT Support
One of the most consequential decisions a growing business makes about IT is whether to stay with reactive, break-fix support or move to a model where someone is watching your systems and catching problems before they cause outages.
Break-fix IT has a clear business case when your IT needs are truly minimal. But once you’re running a team that depends on consistent access to cloud applications, shared file systems, and business-critical software, the math changes. Each incident that could have been prevented carries a real cost — in lost staff hours, in delayed work, and occasionally in data that can’t be fully recovered.
For growing businesses in Texas that have crossed that threshold, working with outsourced IT support options in Dallas or Austin can provide the monitoring, documentation, and vendor coordination that makes downtime less frequent and less severe.
The decision isn’t purely about cost. It’s about whether your current setup can keep up with the demands you’re already placing on it — and whether you’ll find out it can’t before or after a serious incident.
What This Means for Your Business
Reducing business downtime from IT issues doesn’t require a complete overhaul. It requires identifying which gaps in your current setup are most likely to cause an outage, and addressing them in a practical order.
Start with the questions that matter most: When did you last test a real backup restoration? Do you know how long recovery would take if your primary systems went down today? Does anyone on your team own network monitoring, or does monitoring only happen when someone notices a problem?
If those questions don’t have clear answers, that’s where the work begins.
TECHZN works with growing businesses in Dallas and Austin to build reliable, well-documented IT environments that hold up under real operating conditions. If you’re not confident your current IT setup can prevent the next outage, reach out to our team to talk through what a stronger foundation would look like for your business.