Downtime rarely announces itself. It usually shows up as a frozen screen, a dropped VPN connection, a file that won’t open, or a phone system that goes quiet at the worst possible moment. For most small and midsize businesses, the real cost isn’t the outage itself — it’s the hours employees spend waiting, workaround attempts that create new problems, and the operational debt that builds up when nothing gets properly fixed.
If your team regularly deals with recurring IT problems, this guide walks through the most common causes of business downtime from IT issues and what you can actually do to reduce them.
The Most Common IT Problems That Cause Downtime
Not all IT problems are created equal. Some are one-time nuisances. Others are symptoms of deeper gaps that will keep surfacing until someone addresses the root cause.
Here are the patterns that tend to cost businesses the most time:
- Recurring network issues — an office where the internet drops weekly, usually during peak hours, is a sign that the connection has never been properly evaluated for actual business load
- Single points of failure — one internet circuit, one aging server, or one unmonitored device that everything else depends on
- Microsoft 365 problems — access issues, email delivery failures, or misconfigured SharePoint permissions that slow down whole departments
- Backup failures discovered too late — backups that appear to be running but haven’t successfully completed a real restore in months
- Unmanaged devices on the network — personal laptops or old equipment that nobody inventories until they cause a problem
Many of these issues share a common thread: they were either never properly set up or they’ve been patched repeatedly without anyone identifying why they keep happening.
The Hidden Cost of Waiting for Things to Break
One of the most common mistakes growing businesses make is treating IT support as something that only needs to happen after something breaks. This approach — sometimes called break-fix — works when your technology footprint is small and outages are infrequent. It stops working when your team grows, your systems get more interdependent, and your customers expect consistent availability.
Consider a straightforward example: a seven-person accounting team that loses access to their cloud billing application for three hours because a Microsoft 365 authentication setting changed after a routine update. Nobody monitors for that kind of configuration drift. There’s no help desk to call. The office manager spends two hours on hold with Microsoft support, and the team loses half a billing cycle’s momentum.
That scenario plays out regularly in offices that haven’t moved beyond reactive IT. The fix isn’t always expensive — but it requires someone to be watching before things go wrong.
Proactive monitoring matters more than most business owners expect. Network monitoring tools can detect unusual traffic, a failing drive, or a configuration change before employees ever notice a problem. Without them, the first alert you get is a frustrated phone call from someone who can’t do their job.
How to Identify What’s Actually Causing Your Downtime
Before you can reduce downtime, you need to understand where it’s coming from. A lot of businesses skip this step and jump straight to buying new equipment or changing providers — without solving the actual problem.
A basic IT downtime review should cover:
Review your incident history
If your IT support team or vendor isn’t giving you a monthly summary of tickets, outages, and repeat issues, ask for one. Patterns matter. If the same three users are logging tickets every month about the same application, that’s not a user problem — it’s a configuration problem.
Map your single points of failure
Ask your IT team to walk you through what happens if your internet connection goes down, your main server fails, or your Microsoft 365 tenant gets locked out. If the answer is “everything stops,” you have risk that needs to be addressed.
Test your backups
This is the most overlooked item on most business IT checklists. Backup monitoring tells you whether a backup ran. Backup testing tells you whether you can actually recover from it. Those are very different things. A backup that hasn’t been restore-tested with real data is not a reliable safety net.
Check who owns what
In businesses with multiple IT vendors — one for internet, one for phones, one for software — it’s common for problems to fall through the gaps because each vendor assumes another is responsible. Define ownership clearly, especially for anything that crosses systems.
Practical Steps to Reduce Recurring IT Disruptions
Once you know where your downtime is coming from, most of the fixes fall into a few categories:
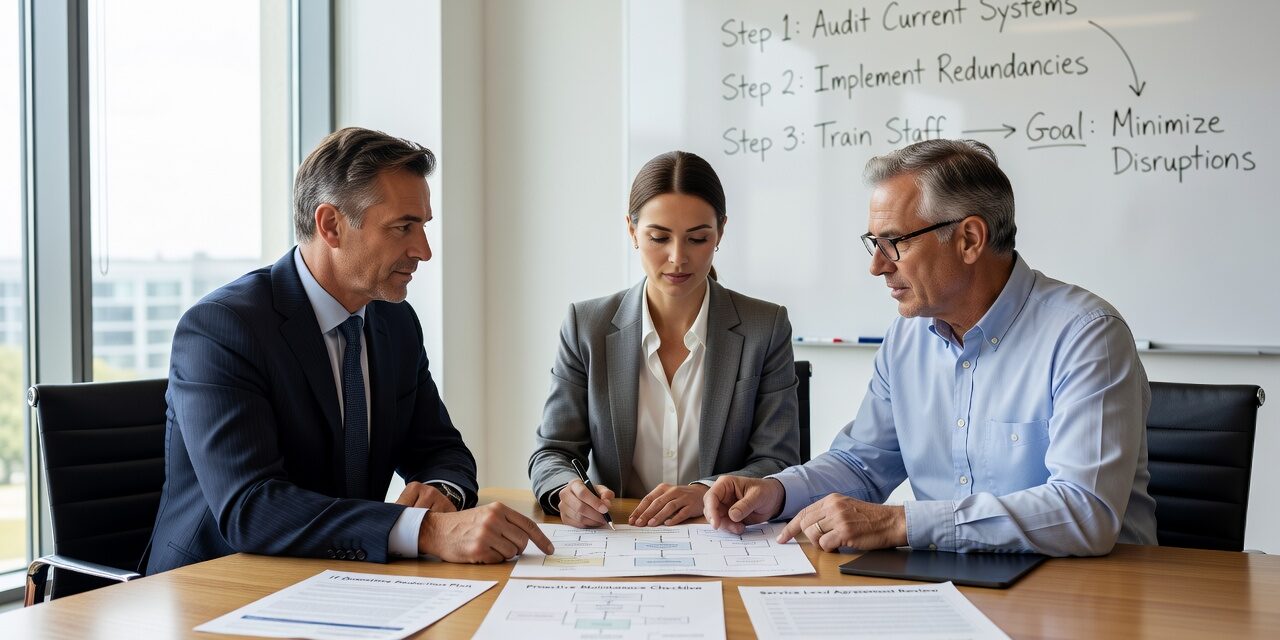
Fix configuration drift before it causes outages. Microsoft 365 settings, firewall rules, and network configurations change over time — sometimes from updates, sometimes from well-meaning internal changes. Regular configuration reviews catch problems before they affect users.
Add redundancy where the risk justifies it. Not every business needs a failover internet circuit, but if your operations depend entirely on a single broadband connection and an outage costs you $5,000 an hour, a secondary LTE connection is a straightforward investment. The same logic applies to servers, switches, and power.
Define what “urgent” means before a crisis hits. When everything feels urgent, nothing gets prioritized. Work with your IT team to define which systems are business-critical — billing, customer communications, operations platforms — and which can wait. That list should drive your recovery order if something major goes down.
Document your recovery plan and test it with employees. A disaster recovery plan that only lives in a PDF is not a working plan. The people who need to follow it during an outage should know it exists and understand their role in it. Even a basic tabletop exercise once a year reveals gaps that would otherwise surface at the worst possible time.
For businesses that don’t have the internal staff to manage all of this consistently, working with outsourced IT support options can provide the ongoing monitoring and response capability that break-fix arrangements don’t.
What This Means for Your Business
Reducing downtime from IT issues isn’t about buying better equipment or finding a faster help desk. It’s about understanding where your operations are most exposed, fixing the problems that keep coming back, and making sure someone is watching your systems before your employees start reporting problems.
The businesses that handle IT disruptions well aren’t necessarily the ones with the biggest IT budgets. They’re the ones that treat technology reliability as an operational priority — not an afterthought.
If you’re not sure where your biggest gaps are, TECHZN works with businesses across Dallas and Austin to identify exactly that. Whether you need a full IT assessment or managed IT support for growing businesses, we can help you build a more reliable foundation. Reach out to start the conversation.