Downtime rarely arrives with a warning. A router fails during a busy morning, Microsoft 365 locks out half your staff, or a failed backup goes unnoticed until you actually need it. For most small and midsize businesses, the question isn’t whether IT problems will cause disruptions—it’s whether those disruptions were preventable.
Learning how to reduce business downtime from IT issues starts with understanding where the real gaps tend to be. Most of them aren’t exotic. They’re ordinary problems that build up quietly over time.
The Difference Between Reactive and Preventive IT Support
Many businesses operate on what the industry calls break-fix support: something stops working, someone calls for help, and a technician fixes it. That model feels manageable until the same problems start repeating every few weeks.
Reactive support keeps you running. Preventive support keeps you from going down in the first place.
A business running on reactive IT will typically see patterns like:
- The same workstations freezing up repeatedly without a root-cause fix
- Network equipment that hasn’t been reviewed or updated in years
- Backups that run nightly but have never been tested for actual recovery
- Staff submitting the same help desk tickets over and over
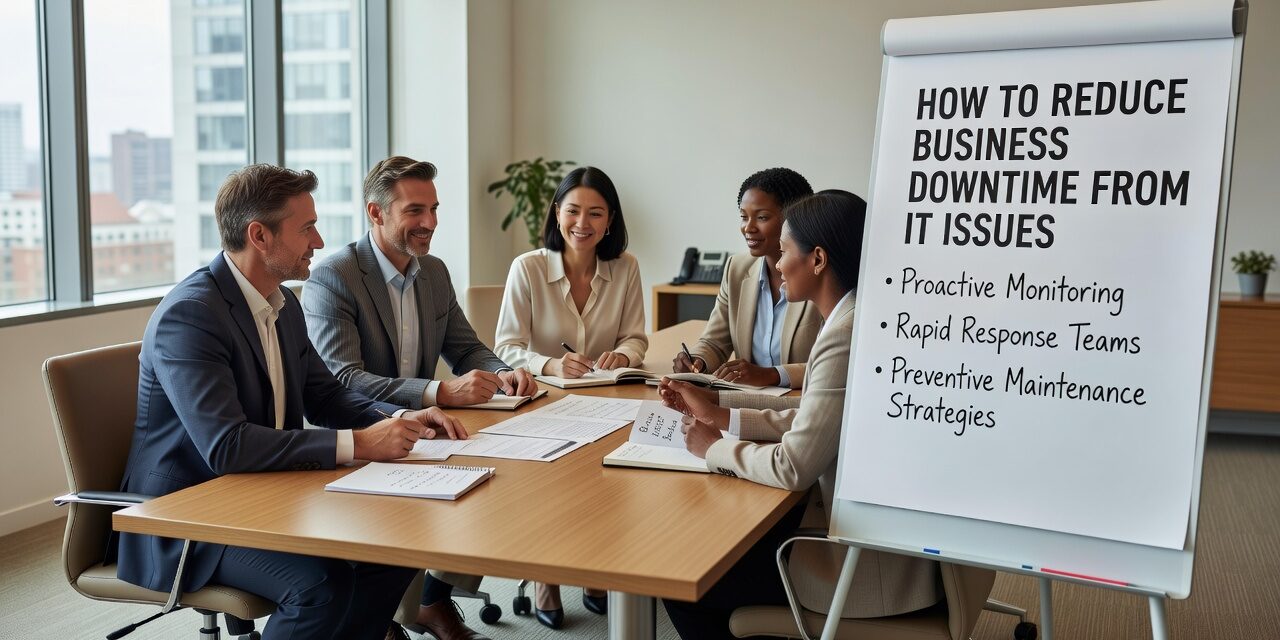
If your IT support is only engaged when something breaks, you’re essentially waiting for problems to cost you time and money before addressing them. Preventive support means someone is actively monitoring systems, catching problems early, and scheduling maintenance before things fail.
Ask your current IT provider or internal team: When did we last review our network equipment? When did we last test a backup restore? If the answers are vague, that’s a real gap.
Common IT Problems That Cause the Most Downtime
Not all IT issues are equally disruptive. Some cause brief annoyances. Others can knock a business offline for hours—or longer.
Aging or unmonitored network equipment
A failing switch or access point can slow down an entire office without triggering an obvious error. Staff notice things feel sluggish. Video calls drop. File transfers take longer. By the time the root cause is identified, a half-day may already be lost. Network equipment has a lifecycle, and businesses that don’t track it regularly end up replacing hardware in emergency situations rather than on a planned schedule.
Backup failures that go undetected
A completed backup job is not the same as a recoverable backup. Many businesses receive nightly confirmation that backups ran successfully—and only discover those backups were incomplete or corrupted when they need to restore files after an incident. Testing a backup restore at least quarterly is one of the most practical things a business can do to avoid a full-blown crisis after hardware failure or a ransomware event.
Single points of failure in internet connectivity
If your business runs on a single internet connection with no secondary failover, a service outage from your ISP can halt operations completely. For businesses that rely on cloud-hosted applications, VoIP phone systems, or remote staff, even a one-hour outage has real financial and operational consequences. A secondary connection—even a cellular backup—can keep critical functions running while the primary line is restored.
Microsoft 365 access and configuration issues
Microsoft 365 is reliable as a platform, but it has settings that require ongoing attention. Accounts that haven’t been properly offboarded after an employee departure, missing multifactor authentication on admin accounts, and misconfigured sharing permissions in SharePoint or OneDrive all create both security exposure and operational risk. When a key account gets locked or compromised, the disruption to daily work can be significant.
A Common Blind Spot: Confusing Data Storage With Recovery Readiness
One of the most consistent mistakes businesses make is assuming that because their data is stored somewhere—a cloud drive, a backup appliance, an external hard drive—they can recover from a serious incident quickly.
Data availability and business recovery are not the same thing.
Consider a scenario where a ransomware event encrypts your file server on a Tuesday morning. You have backups. But do you know which systems need to be restored first? Who makes that call? Does your team know the process, or will they spend the first two hours figuring out who to contact?
A practical recovery plan answers those questions before the incident happens. It identifies the systems that must come back online first, documents the steps for restoring them, and assigns clear ownership. It also gets tested—at least once a year—so that when something goes wrong, the response is practiced rather than improvised.
How to Identify Where Your Business Is Most Exposed
You don’t need a full IT audit to start reducing downtime risk. A few practical questions can point you toward the most important gaps:
- Network equipment age: Are your switches, firewalls, and access points within a reasonable lifecycle? Most network hardware has a realistic lifespan of five to seven years. Equipment past that window becomes a reliability risk.
- Monitoring coverage: Is anyone actively monitoring your servers, network, and endpoints for warning signs, or does your team only find out something is wrong when a user reports it?
- Help desk patterns: If you track IT support tickets, do the same problems appear repeatedly? Recurring tickets are often a sign of unresolved root causes, not isolated incidents.
- Vendor clarity: Do you have multiple IT vendors who each handle different things, with no one person owning the overall picture? Multi-vendor environments often create gaps that nobody catches because everyone assumes someone else is handling it.
- Recovery testing: When did you last simulate a restore from backup? If you can’t answer that question, it’s worth prioritizing.
For growing businesses without a dedicated internal IT team, these gaps tend to accumulate faster than they’re noticed. Outsourced IT support for growing businesses typically includes monitoring, lifecycle planning, and help desk coverage under one agreement—which removes the coordination problem that causes many of these gaps in the first place.
What This Means for Your Business
Most IT-related downtime is preventable. Not all of it, but enough of it that a structured, proactive approach to IT management makes a measurable difference in how often your operations are disrupted and how quickly you recover when something does go wrong.
The practical starting point is honest visibility: know what’s in your environment, know who’s monitoring it, and know what your recovery process actually looks like under pressure.
If your current IT setup doesn’t give you clear answers to those questions, TECHZN can help. We work with businesses across Dallas and Austin to close the gaps that lead to downtime—through proactive monitoring, structured support agreements, and recovery planning that gets tested before it’s needed. Reach out to our team to talk through where your business stands.